Design

An autonomous excavator on a job site slowed itself down. No fault, no alarm. Its safety system had been tripped by a dirty sensor, decided it was seeing an obstruction, and did exactly what it was designed to do. The robot was working correctly. The site was just being a site, with dirt. They all have dirt.
That is a small incident, and it is representative of many things a robotics fleet runs into once it leaves the test environment. In this case, and in others like it, the data to explain the issue existed on the machine. The engineers could have pulled it. But the person standing there was a field operator, and there was nothing between the operator console and the engineering debug tools that would let them see what the robot had seen and make a call.
Every Physical AI system runs on a chain of handoffs. The environment hands the machine a reading. The machine hands the operator a behavior. The operator hands the engineer a question. Most of the off-robot software we build at Andes Path sits at one of those seams, and this incident sat on the last one: the machine knew what it had seen, the operator could see what it was doing, and nothing connected the two so that a person could decide what to do next.
In this video, Steve and Clark, our co-founders, with Fernando, one of the engineers on the project, talk through the operations and support layer we built for this client. This post is the longer version of why that layer keeps turning up as the missing piece in so many Physical AI projects, whatever the machine, and how we approach building systems like this.
Early fleets get supported directly by the engineers who built them. Five or ten robots in the field, and the team can debug on the go, learn from every incident, and dogfood their own tooling. It works, and it is genuinely the right way to run a fleet at that stage because the learning is so dense.
Past a certain fleet size, the same arrangement starts consuming the engineering team. Every incident becomes an interrupt. Autonomy engineers spend afternoons explaining sensor logs to support staff. The organization needs an operations layer, with its own tools and its own workflows, and building it is a real engineering project that nobody planned for.
From inside the company it rarely looks like a tooling gap. It looks like growth stalling, engineering slowing down, and the same handful of errors coming back week after week. We have seen that pattern in excavators, in warehouse robots, in delivery fleets and in factory cells, and it is the same pattern. For this client, we built the missing layer and, for a period, we also ran it for them.
The operator experience is built to run the machine. Engineering tools are built to develop and debug it. Support sits between them and usually inherits nothing from either side, which is why so much fleet support runs on phone calls, text messages, Slack threads, and screenshots.
We started by working alongside the client's engineers on live incidents, watching how they investigated each one. Which telemetry they pulled first. What they looked at on the map. How they decided a slowdown was an obstruction reading rather than a planner fault or a full blown hardware malfunction. We had to figure out what they needed to know before they would trust an operator to clear it and carry on. That investigative process, repeated across many incidents, is the actual specification for a support tool. It exists in the engineers' heads long before it exists anywhere else.
Nothing about that method depends on the machine being an excavator. Whatever the fleet does, the diagnostic path its best engineer follows under pressure is the product we were hired to build, and the fastest way to write it down is to watch it happen.
The first version was in front of the support team in about a week. That speed matters less as a benchmark than as a method. A support tool built for a growing fleet has to be in use early, because the fleet keeps producing new failure modes and the tool has to grow alongside them.
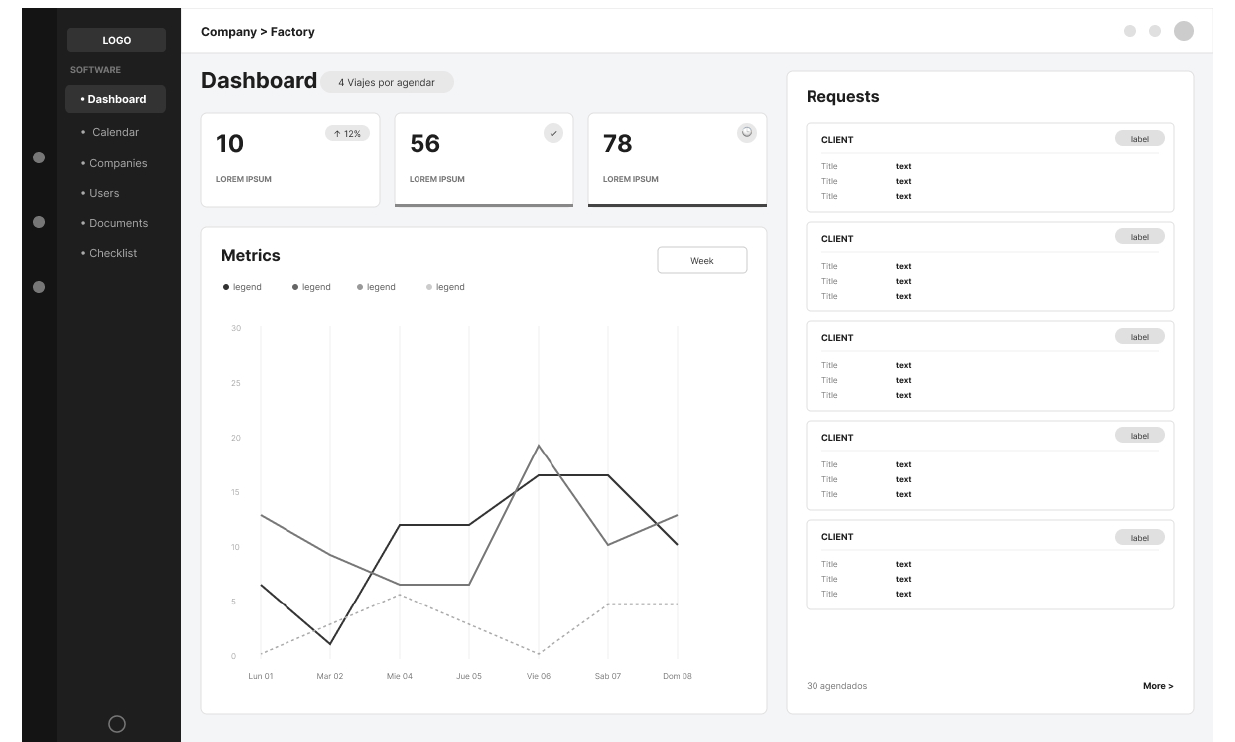
The core was live fleet state, telemetry, and incident history, presented with enough context that a support operator could explore what happened and either resolve it on the spot or escalate with something an engineer could act on immediately. The dirt-as-obstruction workflow was one small example among many. As their fleet grew, our team kept extending the diagnostics and custom workflows as operations discovered what it needed, working directly with the client's engineers as new problems showed up.
The scope widened from there into a custom planner built around how an excavator actually moves earth, and a set of civil engineering views so that the people managing the site could see progress in their own terms, rather than robot coordinates.
For an engineering leader, the calculation is usually about where their scarce autonomy engineers spend their time. Every hour on a support escalation is an hour off the roadmap, and the escalations scale with the fleet. A support layer that lets operations resolve the common cases, and hands engineering only the ones that need them with full context attached, changes the cost of those escalations.
It also changes what the organization can see. Once live state, telemetry, and incident history are in one place, the same foundation serves operations, support, customer reporting, and the engineers themselves. The tooling stops being a favor from the autonomy team and becomes infrastructure.
The excavator is incidental to all of this. Swap it for a harvester, a fleet of warehouse robots, a sidewalk delivery vehicle, or an inspection drone and the handoffs are the same: the environment produces a reading, the machine produces a behavior, the operator produces a question, and someone has to be able to answer it without waking up the person who wrote the planner. What changes between industries is the telemetry, the vocabulary and the people standing there. What does not change is that the layer connecting them has to be built, and that it is almost never on the roadmap.
The client's engineers got their time back. Their support team can diagnose and clear most field incidents without an engineer in the loop, and the ones that do escalate arrive with the context already assembled. The fleet kept growing, and the tooling grew with it.
We see this class of problem pretty frequently. The autonomy is capable, but the software that should sit between what the machine knows and what the rest of the company can use is missing, because it was never anyone's job to build it. That is the off-robot software we build alongside robotics teams, at whichever handoff is breaking. Watch the video to hear how the team approached it. If you run machines of any kind and find yourself facing operational or scaling problems you can't fully explain, we should talk.
Insights